Fewer Bytes, More Tokens: How Qwen3.8-27B Decodes Six Times Faster on a DGX Spark

The DGX Spark reads memory at 273 GB/s, which caps plain decoding of a dense 27B model at about 14 tokens per second however much compute sits behind it. Measured on one Spark, Qwen3.8-27B decodes at 11.4 tokens per second without speculation and, for the median request, at 67.8 with the Chisel recipe. Every step between the two either reduces the bytes read per decode step or raises the tokens produced per step, and this post measures each one separately.
October 31, 2026 · 20 min · MdJawad

Why Decode Wants 64 GPUs: Tokens per Expert and the MoE Roofline

A mixture-of-experts model decodes efficiently only when each expert processes many tokens for every read of its weights, and top-k routing divides the batch by the ratio of experts to active experts before any expert sees it. DeepSeek serves V4.1-Flash decode on 64 to 128 GPUs because spreading the experts that widely pools every GPU’s tokens into each expert. We derive the quantity that governs this, place one expert on the GB200 roofline, and predict DeepSeek’s measured EP8 decode curve from its EP64 curve to within 6% with no fitted constants.

October 25, 2026 · 26 min · MdJawad

Kimi K3's Architecture: Kimi Delta Attention, Attention Residuals, and 896 Experts

Softmax costs O(n squared), so what you can afford depends only on how long the axis is. Kimi K3 drops softmax attention from three sequence layers in every four, and in the same model buys it on the depth axis. We derive the delta rule behind Kimi Delta Attention, work out why its decay carries a floor of exactly -5, unroll a residual connection to see what Attention Residuals replaces, and follow quantile balancing back to the dual it solves.

August 11, 2026 · 32 min · MdJawad

The Evolution of Attention, Part 1: From MHA to Latent Compression

Part 1 of 2. Every attention variant since 2019 fights the same number: KV cache bytes per token. This post traces the first wave of answers, from MHA through MQA and GQA, to DeepSeek-V2’s Multi-head Latent Attention. We end at the 57× cache reduction that comes from caching a low-rank latent and never materializing K or V at inference.

May 17, 2026 · 19 min · MdJawad

State Space Models and the Mamba Architecture: From First Principles to Mamba-3

NVIDIA’s Nemotron-3-Super, IBM’s Granite, and AI21’s Jamba all ship hybrid SSM-Transformer architectures in production. This post builds State Space Models from scratch, starting with a single differential equation, and works up through HiPPO, S4, and the three generations of Mamba to explain why.

March 22, 2026 · 33 min · MdJawad

Speculative Speculative Decoding: Eliminating the Last Sequential Bottleneck in LLM Inference

How speculating about speculation itself achieves up to 5x faster LLM inference by eliminating the draft model’s idle time during verification, and the three engineering challenges that make it work.

March 7, 2026 · 21 min · MdJawad

Why `vllm serve` Works on Day Zero (and What It Takes to Make It Fast)

A deep dive into vLLM’s tiered model integration — from the Transformers fallback that enables zero-day support to the native integration path that makes it fast.

February 14, 2026 · 20 min · MdJawad
Orchestra conductor coordinating musicians in a circular arrangement

Orchestrating Inference: How Kubernetes, Ray, and vLLM Coordinate Under the Hood

A deep dive into how Kubernetes, Ray, and vLLM coordinate to transform independent GPUs into a synchronized inference machine.

January 18, 2026 · 19 min · MdJawad
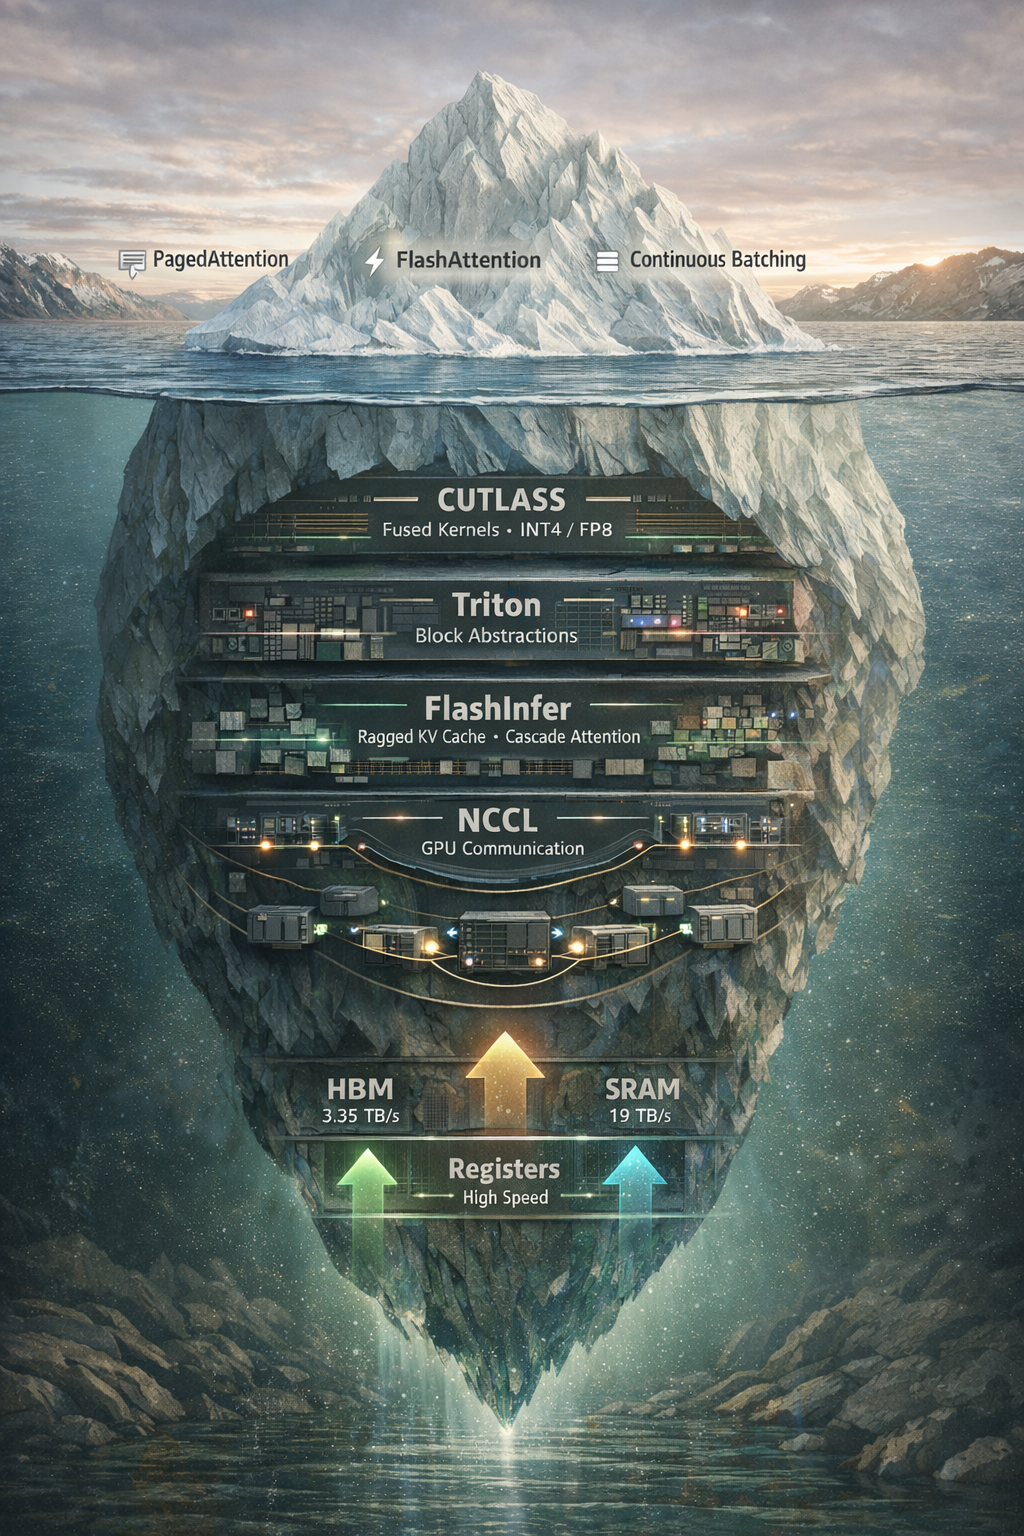
Iceberg visualization showing the hidden software stack behind LLM inference

The Hidden Software Stack Behind Fast LLM Inference

Beyond vLLM and PagedAttention: exploring NCCL, CUTLASS, Triton, and FlashInfer, the libraries that actually make LLM inference fast.

January 10, 2026 · 12 min · MdJawad

Speculative Decoding: When Guessing Right Makes for Faster Inference

How speculative decoding achieves 2-3× inference speedup without changing model outputs, and why GLM-4.7’s native multi-token prediction marks a paradigm shift.

December 23, 2025 · 20 min · MdJawad